OpenNWM
A Generalist Navigation World Model
with Latent Action Pretraining
NavAnywhere
01 / OVERVIEW
Overview of OpenNWM
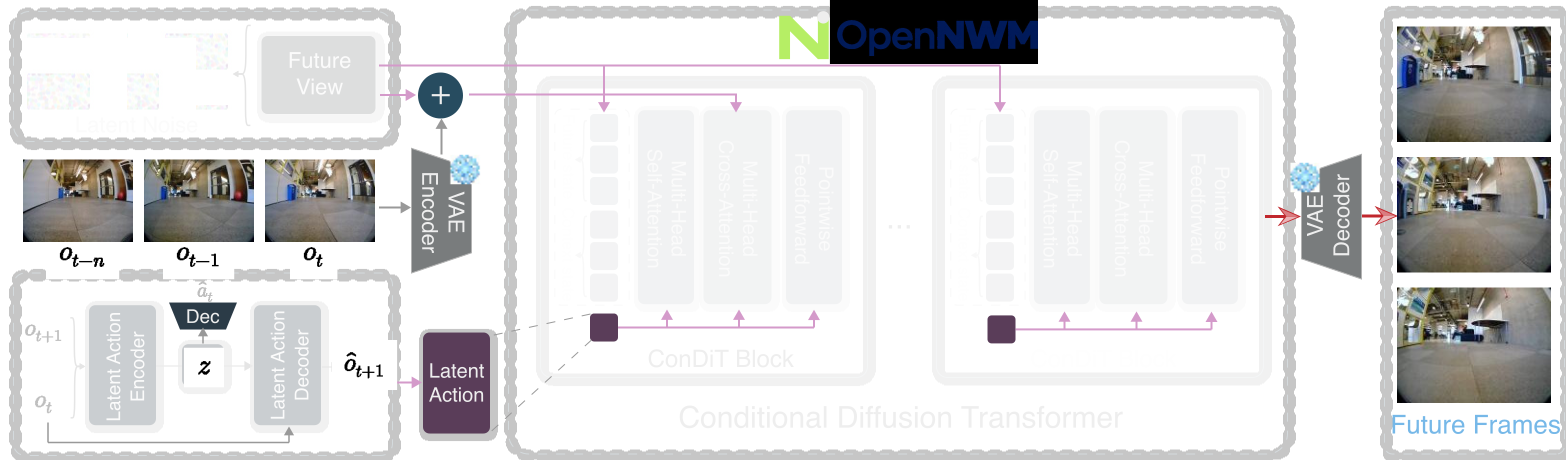
02 / MAIN RESULTS
Future prediction & navigation
04 / VISUALIZATION
Visualization
Predicted views along given paths, followed by offline plans toward visual goals.
Future prediction
05 / DemoYour path.
Your path.
An imagined future.
Choose a scene and a path. Let OpenNWM imagine the view ahead.
01 — DRAW YOUR PATH
FORWARD ↑Drag from the starting point
02 — IMAGINE THE VIEWSTARTING VIEW
A new journey starts here
06 / NavAnywhere Dataset
Different worlds.
Different worlds.
A common language.
Streets, homes, gardens, and paths less traveled. Navigation experience across people, robots, and drones.
Explore the dataset17.5Mvisual observations
15pretraining sources
70.8Knavigation sequences
KEEP EXPLORING
The next step
The next step
starts here.
A Generalist Navigation World Model with Latent Action Pretraining
REFERENCE THIS WORK
@misc{nie2026opennwmgeneralistnavigationworld,
      title={OpenNWM: A Generalist Navigation World Model with Latent Action Pretraining},
      author={Dujun Nie and Ruiqi Song and Zixuan Wang and Hanqing Wang and Yifan Han and Baiyong Ding and Wenzhao Zheng and Hangbin Wu and Long Chen},
      year={2026},
      eprint={2611.01844},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2611.01844},
}
arXiv:2611.01844 · 2026.